Skill
Transformers & LLMs
Attention, tokens, and why next-token prediction scales.
Do these first
What you will be able to do
- Explain self-attention in one paragraph
- Tokenize a sentence and estimate context length
- Train a tiny GPT on a toy corpus (Karpathy)
Curated resources
Start with the pick, then branch out
Scores are LearnPath editorial opinions (clarity, cost, freshness, project density) — not an objective ranking. Every YouTube item is embedded officially after a click-to-load facade.
 2hAdvanced
LearnPath pickyoutube courseadvanced
Let's build GPT from scratch
Andrej Karpathy2h
Type every line. This is the best public transformer lesson we know.
Score 98
WatchOfficial docs
Alternativeinteractiveintermediate
Hugging Face NLP course
Hugging Face8h
Free. Chapters 1–4 cover the stack you will actually use.
Score 94
Open 1hBest for beginners
Quick pathyoutube videobeginner
[1hr Talk] Intro to Large Language Models
Andrej Karpathy1h
The one-hour talk that defined the genre: what an LLM is, how it is trained, what it can and cannot do, and how to think about security and tool use. Non-technical enough for product and business readers while staying accurate.
Score 76
Watch 30h 18mProject-based
Project-orientedyoutube courseintermediate
Generative AI Full Course – Gemini Pro, OpenAI, Llama, Langchain, Pinecone, Vector Databases & More
freeCodeCamp.org30h 18m
Thirty hours of project-based generative AI — Gemini, OpenAI, Llama, LangChain, Pinecone, vector databases — with many small applications built. Use it as a project catalogue: pick the ones that match your roadmap rather than watching linearly.
Score 79
Watch 3h 31m
More curatedyoutube courseintermediate
Deep Dive into LLMs like ChatGPT
Andrej Karpathy3h 31m
Three and a half hours covering the entire life of a modern LLM — pretraining, supervised fine-tuning, reinforcement learning, tokenisation, hallucinations and tool use — with demos of each stage. Published February 2025, it is the most current deep overview from someone who has trained these models.
Score 86
Watch 22h 54mLearnPath pick
More curatedyoutube coursebeginner
GenAI Essentials – Full Course for Beginners
freeCodeCamp.org22h 54m
Twenty-three hours published January 2025 covering the whole generative AI stack — model landscape, prompting, embeddings, RAG, agents, evaluation — as one coherent curriculum. The best single video to understand the entire field's vocabulary in context.
Score 81
Watch 21h 11m
More curatedyoutube courseintermediate
Generative AI for Developers – Comprehensive Course
freeCodeCamp.org21h 11m
Twenty-one hours aimed squarely at developers: APIs, embeddings, vector stores, RAG and agents with code from the first hour. More engineering-dense than the essentials course.
Score 81
Watch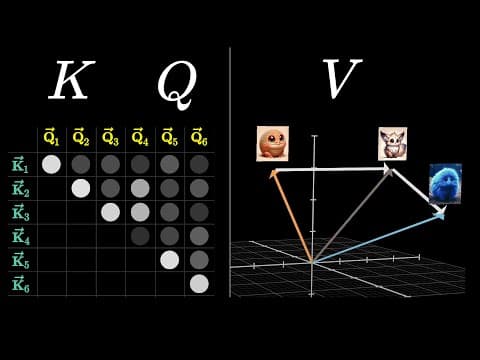 26 minAdvanced
More curatedyoutube videointermediate
Attention in transformers, step-by-step | Deep Learning Chapter 6
3Blue1Brown26 min
The step-by-step companion to the transformer chapter: queries, keys, values, masking and multi-head attention worked through with equations and animation. The clearest treatment of the mechanism itself.
Score 79
Watch 27 min
More curatedyoutube videointermediate
Transformers, the tech behind LLMs | Deep Learning Chapter 5
3Blue1Brown27 min
Twenty-seven minutes that make attention and the transformer block visually obvious — the architecture behind every modern LLM. Watch this before any LLM engineering work and the engineering literature becomes readable.
Score 78
Watch 2h 57mProject-based
More curatedyoutube videointermediate
Ollama Course – Build AI Apps Locally
freeCodeCamp.org2h 57m
Builds working apps against locally hosted models with Ollama — chat with your documents, a coding assistant, vision and an image-generation pipeline — with no API keys and no per-token cost. Essential counterweight to the cloud-API tutorials: it teaches the same application patterns while making model hosting, quantisation and privacy trade-offs visible.
Score 77
Watch 23 min
More curatedyoutube videoadvanced
How might LLMs store facts | Deep Learning Chapter 7
3Blue1Brown23 min
Explores how facts might be stored in a model's MLP layers — the most concrete public treatment of what is happening inside an LLM beyond the attention mechanism.
Score 75
Watch 8 minFastest path
More curatedyoutube videobeginner
Large Language Models explained briefly
3Blue1Brown8 min
Eight minutes of the clearest possible explanation of what an LLM is and how it produces text. Ideal first watch in the generative AI category, and short enough to send to a non-technical teammate.
Score 74
Watch 9 minFastest path
More curatedyoutube videobeginner
What is Multimodal AI? How LLMs Process Text, Images, and More
IBM Technology9 min
A 2026 explainer on how models process text, images and audio together, including what multimodal actually enables in products. Fast, accurate orientation for the multimodal skill.
Score 69
WatchApply it
Projects